Dorbit
Dedicated LLM endpoints with lower-cost GPU options
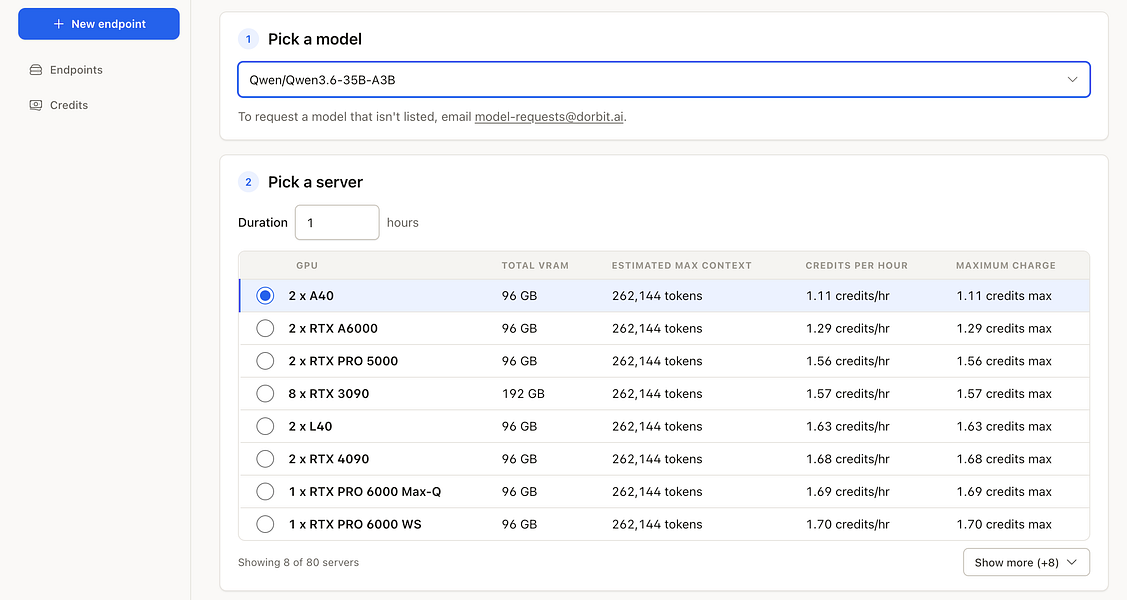
Dorbit lets developers launch open models on dedicated, OpenAI-compatible inference endpoints. You can choose a model, compare GPU configurations, select a duration, and see the maximum charge before launching. Lower-cost GPU options let you start at a lower hourly price when they fit your model and workload. Dorbit handles deployment and reserves your endpoint for your use. Performance and capacity depend on your configuration. Dorbit is in early access. Join the waitlist to try it and help shape the product.