Seply Speaker Split
Split mixed recordings into time-aligned tracks for each speaker
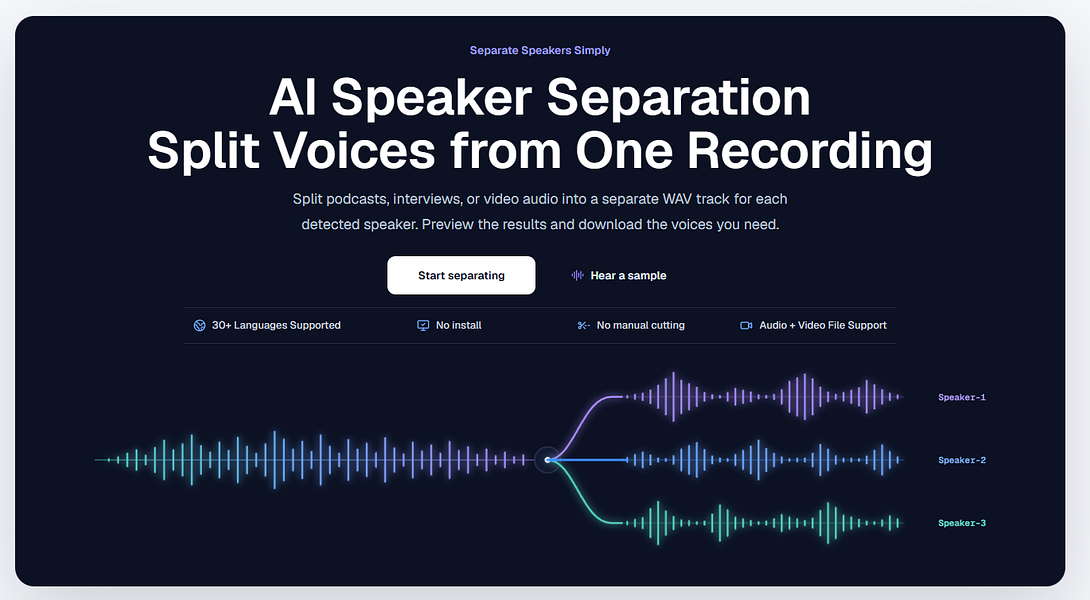
Seply separates a mixed recording into individual, time-aligned tracks for each detected speaker. Upload audio or video, choose automatic or manual speaker detection, and download separate WAV files for each voice. It supports over 30 languages and handles overlapping speech with an advanced mode. Seply also provides speech-to-text transcription with speaker labels, timestamps, and TXT, SRT, VTT, or JSON exports. No software installation is required.


